本文讲述在Jetson NX部署EfficientDet的过程。先介绍EfficientNet的复合模型扩张方法,通过平衡深度、宽度和分辨率提升性能;提及EfficientDet的BiFPN结构。接着说明将动态图转为静态图并导出,测试静态图性能,最后阐述在Jetson NX配置环境及部署流程,其期望FPS为4。
☞☞☞AI 智能聊天, 问答助手, AI 智能搜索, 免费无限量使用 DeepSeek R1 模型☜☜☜
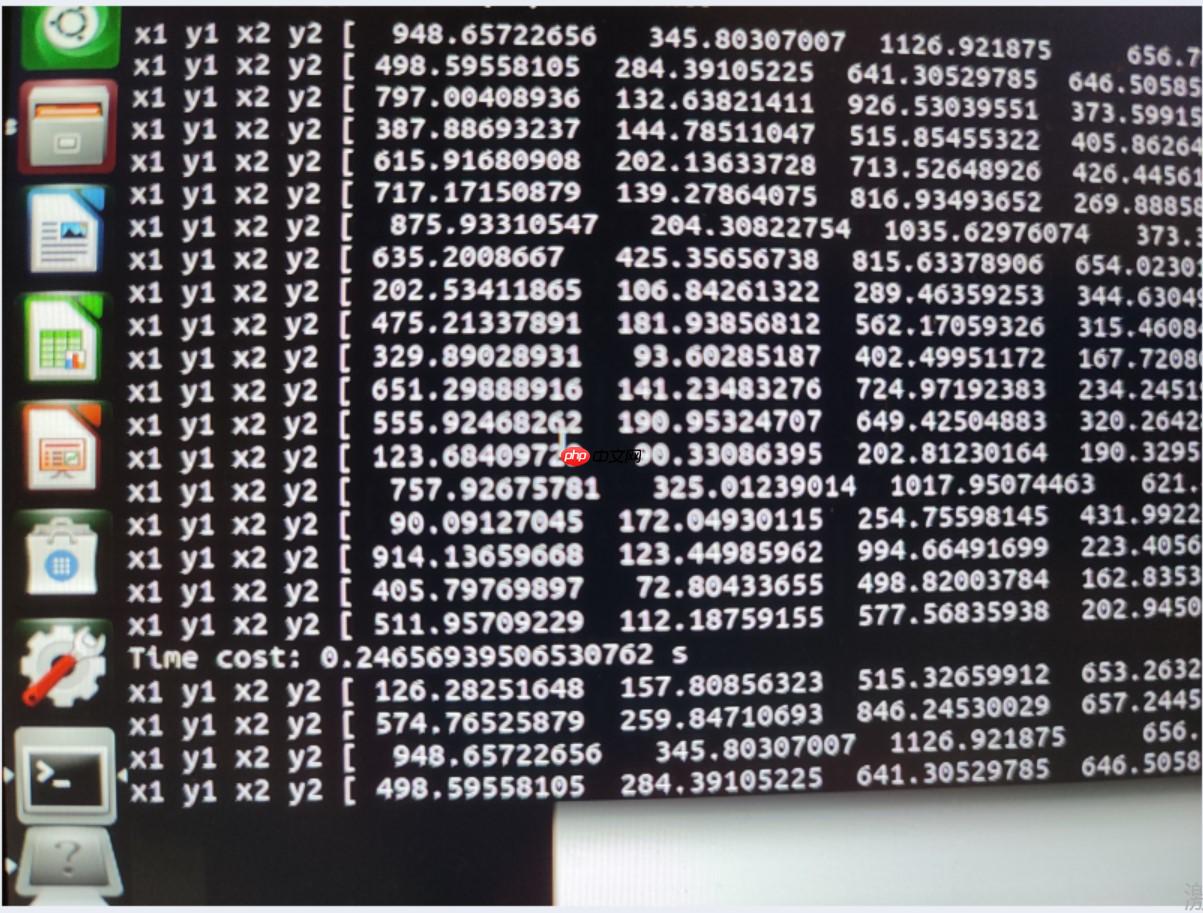
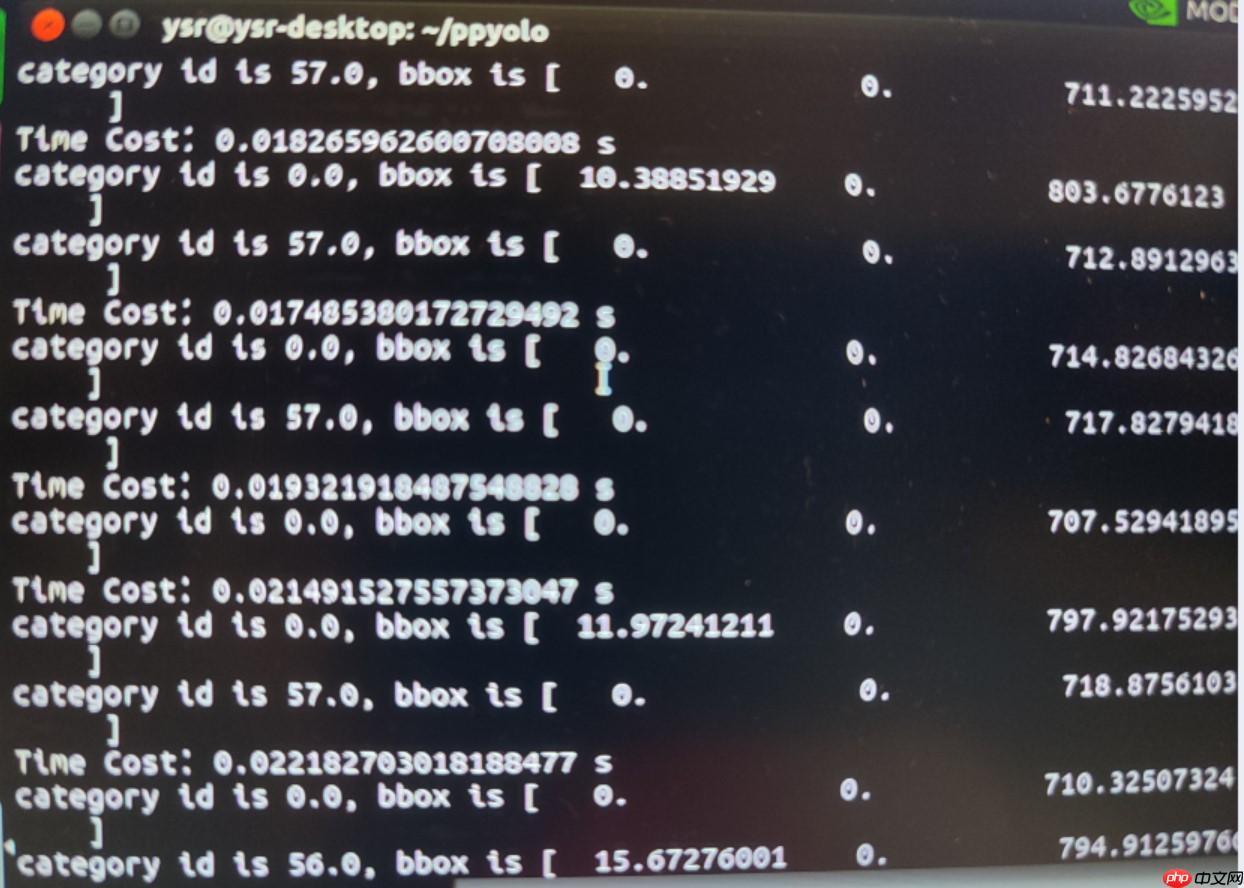
听闻jetson NX的算力很强,前几天部署了ppyolo并跑出了接近100的FPS,于是这几天尝试部署一下efficient。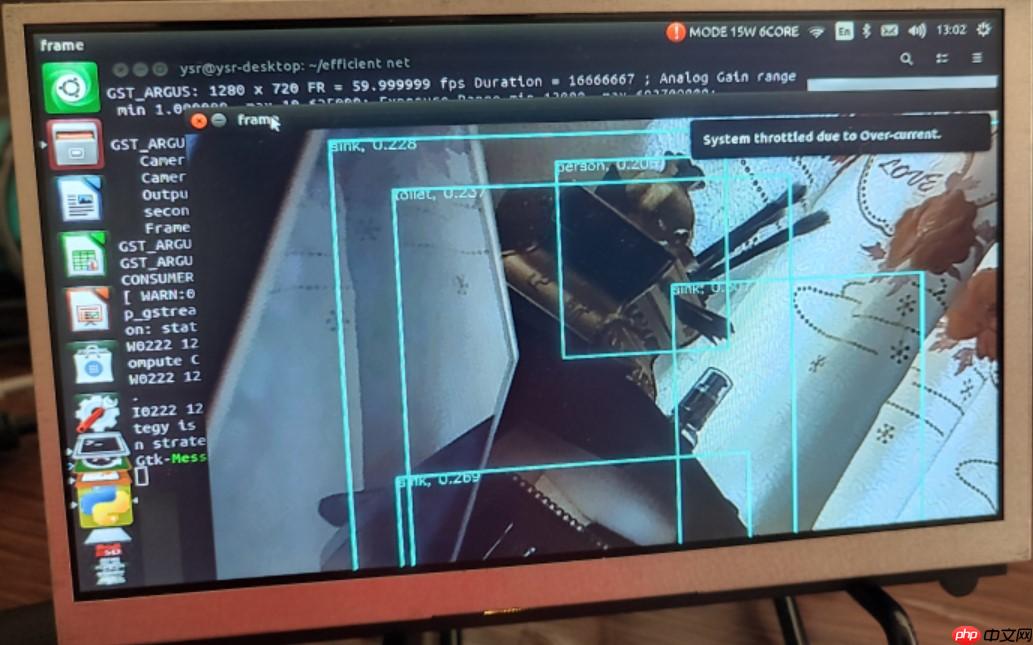
paddle在jetson NX的配置
引用了这位大佬的efficientnet
知乎
卷积神经网络扩大规模以获得更好的精度,比如可以提高网络深度(depth)、网络宽度(width)和输入图像分辨率 (resolution)大小。但是通过人工去调整 depth, width, resolution 的放大或缩小的很困难的,在计算量受限时有放大哪个缩小哪个,这些都是很难去确定的,换句话说,这样的组合空间太大,人力无法穷举。基于上述背景,该论文提出了一种新的模型缩放方法,它使用一个简单而高效的复合系数来从depth, width, resolution 三个维度放大网络,不会像传统的方法那样任意缩放网络的维度,基于神经结构搜索技术可以获得最优的一组参数(复合系数)。从下图可看出,EfficientNet不仅比别的网络快很多,而且精度也更高。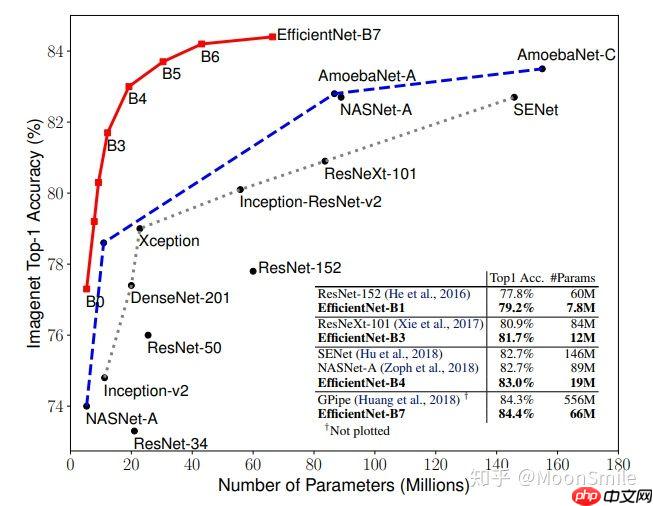
EfficientNet从三个维度均扩大了,但是扩大多少,就是通过作者提出来的复合模型扩张方法结合神经结构搜索技术获得的。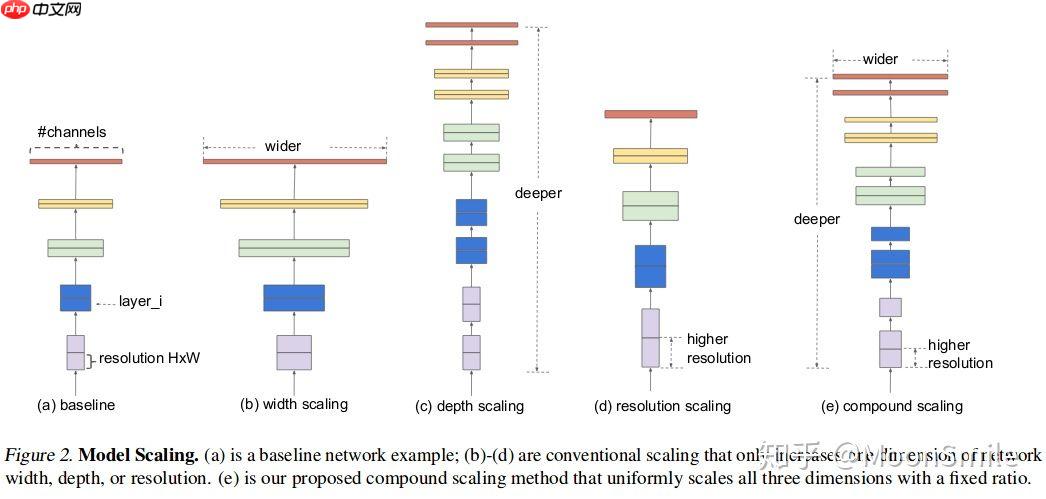
实现最优化目标。 优化目标就是在资源有限的情况下,要最大化 Accuracy, 优化目标的公式表达如下: 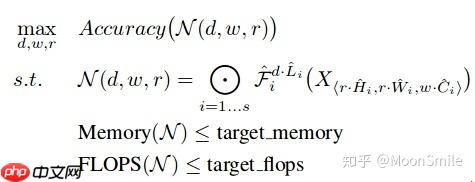 作者发现,更大的网络具有更大的宽度、深度或分辨率,往往可以获得更高的精度,但精度增益在达到80%后会迅速饱和,这表明了只对单一维度进行扩张的局限性,实验结果如下图:
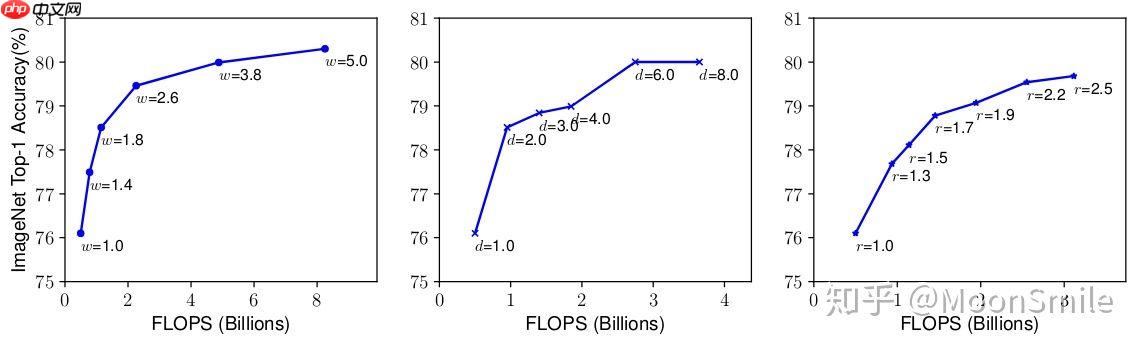
作者指出,模型扩张的各个维度之间并不是完全独立的,比如说,对于更大的分辨率图像,应该使用更深、更宽的网络,这就意味着需要平衡各个扩张维度,而不是在单一维度张扩张。
所以本文提出了复合扩张方法,这也是文章核心的地方。 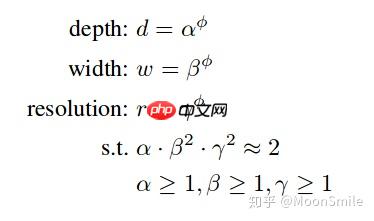
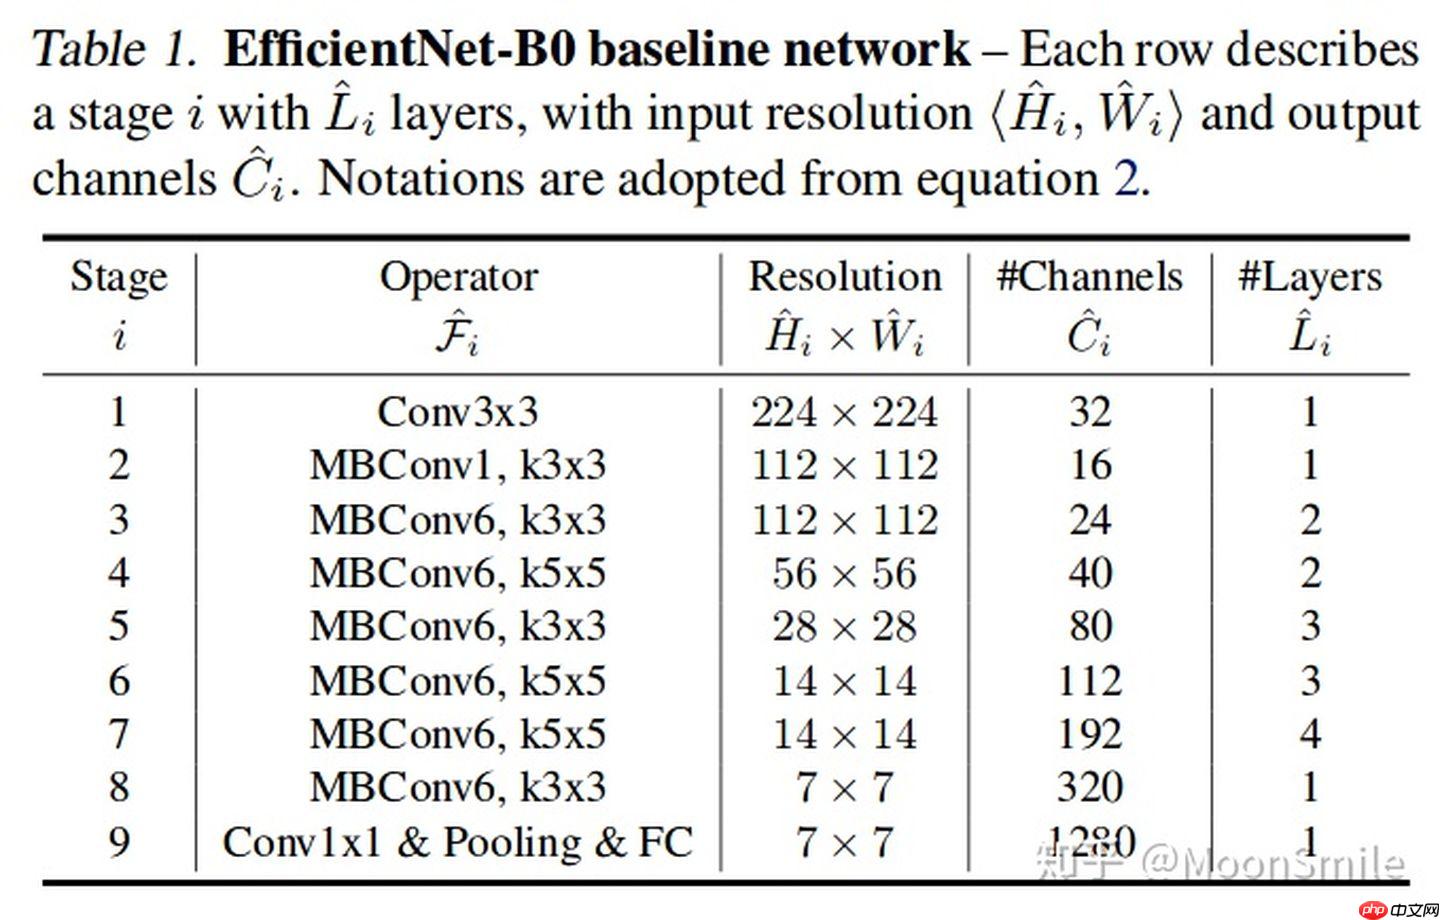
先固定公式中的一个参数,然后求别参数,从而得到基础的d0网络,然后固定其他参数,根据基础网络扩展d1以上的网络
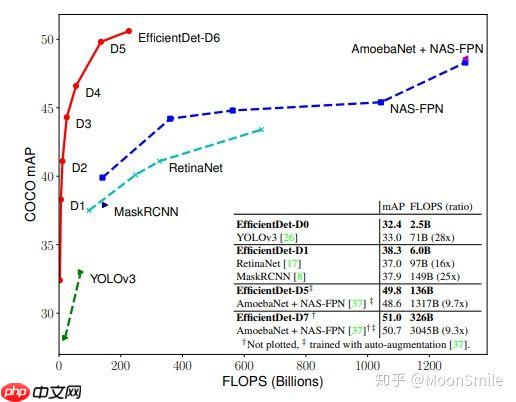
1、如何高效的进行多尺度特征融合(efficient multi-scale feature fusion):提到多尺度融合,在融合不同的输入特征时,以往的研究(FPN以及一些对FPN的改进工作)大多只是没有区别的将特征相加;然而,由于这些不同的输入特征具有不同的分辨率,我们观察到它们对融合输出特征的贡献往往是不平等的,为了解决这一问题,作者提出了一种简单而高效的加权(类似与attention)双向特征金字塔网络(BiFPN),它引入可学习的权值来学习不同输入特征的重要性,同时反复应用自顶向下和自下而上的多尺度特征融合。
2、如何对模型进行扩张(参考上文 EfficientNet ,同时考虑depth、width和resolution)
作者基于EfficientNet, 提出对检测器的backbone等网络进行模型缩放,并且结合提出的BiFPN提出了新的检测器家族,叫做EfficientDet。本文提出的检测器的主要遵循one-stage的设计思想,通过优化网络结构,可以达到更高的效率和精度。
如下图所示,BiFPN在图e的基础上增加了shortcut,这些都是在现有的一些工作的基础上添砖加瓦。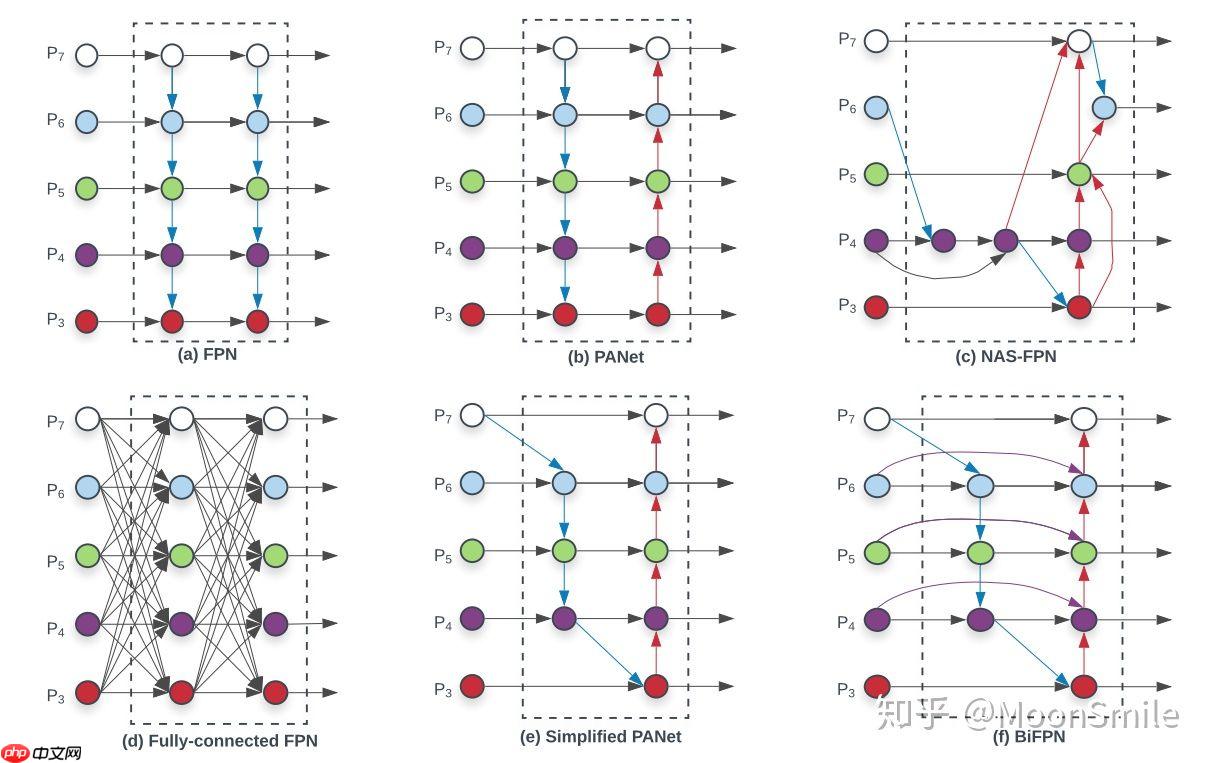
作者提出了快速的限制方法 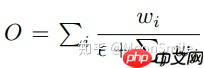
之前的写好的是动态图模式的复现,我们首先要将其转换成静态图模式
In [2]%cd EfficientDet/
/home/aistudio/EfficientDet
安装两个库
 Openflow
一键极速绘图,赋能行业工作流
 88
查看详情
 In [ ]
!pip install pycocotools webcolorsIn [ ]
# 先检查动态图能不能跑通!python b.py
接下来导出静态图
注意,自定义算子的apply无法在静态图里面使用,因此如果要导出静态图,必须要先设置好自定义算子在静态静态图的运动模式
#自定义算子class SwishImplementation(PyLayer):    @staticmethod
    def forward(ctx, i):
        result = i * F.sigmoid(i)
        ctx.s*e_for_backward(i)        return result    @staticmethod
    def backward(ctx, grad_output):
        i = ctx.s*ed_tensor()[0]
        sigmoid_i = F.sigmoid(i)        return grad_output * (sigmoid_i * (1 + i * (1 - sigmoid_i)))
# 动态图模式class MemoryEfficientSwish(nn.Layer):
    def forward(self, x):
        return SwishImplementation.apply(x)
# 静态图的自定义算子的运用class Swish(nn.Layer):
    def forward(self, x):
        return x * F.sigmoid(x)
In [ ]
# 导出静态图import paddleimport cv2import numpy as npfrom backbone import EfficientDetBackbonefrom efficientdet.utils import BBoxTransform, ClipBoxesfrom utils.utils import invert_affine, postprocess, preprocess_videoimport os

compound_coef = 0# 更改compound可以选择efficientDet的版本force_input_size = None  # set None to use default sizethreshold = 0.2iou_threshold = 0.2obj_list = ['person', 'bicycle', 'car', 'motorcycle', 'airplane', 'bus', 'train', 'truck', 'boat', 'traffic light',            'fire hydrant', '', 'stop sign', 'parking meter', 'bench', 'bird', 'cat', 'dog', 'horse', 'sheep',            'cow', 'elephant', 'bear', 'zebra', 'giraffe', '', 'backpack', 'umbrella', '', '', 'handbag', 'tie',            'suitcase', 'frisbee', 'skis', 'snowboard', 'sports ball', 'kite', 'baseball bat', 'baseball glove',            'skateboard', 'surfboard', 'tennis racket', 'bottle', '', 'wine glass', 'cup', 'fork', 'knife', 'spoon',            'bowl', 'banana', 'apple', 'sandwich', 'orange', 'broccoli', 'carrot', 'hot dog', 'pizza', 'donut',            'cake', 'chair', 'couch', 'potted plant', 'bed', '', 'dining table', '', '', 'toilet', '', 'tv',            'laptop', 'mouse', 'remote', 'keyboard', 'cell phone', 'microw*e', 'oven', 'toaster', 'sink',            'refrigerator', '', 'book', 'clock', 'vase', 'scissors', 'teddy bear', 'hair drier',            'toothbrush']# tf bilinear interpolation is different from any other's, just make doinput_sizes = [512, 640, 768, 896, 1024, 1280, 1280, 1536, 1536]
input_size = input_sizes[compound_coef] if force_input_size is None else force_input_size# load modelmodel = EfficientDetBackbone(compound_coef=compound_coef, num_classes=len(obj_list)
,onnx_export=True)
model.set_state_dict(paddle.load(f'weights/efficientdet-d{compound_coef}.pdparams'))
model.eval()
input_spec = paddle.static.InputSpec([1, 3, 512, 512], 'float32', 'image')# input_spec = paddle.static.InputSpec([None, 3, 512, 512], 'float32', 'image')# 填写底下那句,到后面None会被表示成-1,这样如果动态图里面有-1就不行了model = paddle.jit.to_static(model, input_spec=[input_spec])
paddle.jit.s*e(model, 'inference_models/efficientDet')# paddle.onnx.export(model, "inference", input_spec=[input_spec],opset_version=11)# 打印保存的模型文件名print(os.listdir('inference_models'))
注意在设置模型输入类型时,如果动态图模式里,维度大小表示时使用了-1.则输入类型可能不能有-1
点击项目右边的数据可视化,然后选择模型文件为inference_models/efficientDet.pdmodel,然后进入可视化即可
这个模型有点大!
# Core Author: Zylo117# Script's Author: winter2897 """
Simple Inference Script of EfficientDet-Pytorch for detecting objects on webcam
"""import timeimport paddleimport cv2import numpy as npfrom efficientdet.utils import BBoxTransform, ClipBoxesfrom utils.utils import invert_affine, postprocess, preprocess_video# Video's pathvideo_src = 'video.mp4' # set int to use webcam, set str to read from a video filecompound_coef = 0force_input_size = None # set None to use default sizethreshold = 0.2iou_threshold = 0.2obj_list = ['person', 'bicycle', 'car', 'motorcycle', 'airplane', 'bus', 'train', 'truck', 'boat', 'traffic light', 'fire hydrant', '', 'stop sign', 'parking meter', 'bench', 'bird', 'cat', 'dog', 'horse', 'sheep', 'cow', 'elephant', 'bear', 'zebra', 'giraffe', '', 'backpack', 'umbrella', '', '', 'handbag', 'tie', 'suitcase', 'frisbee', 'skis', 'snowboard', 'sports ball', 'kite', 'baseball bat', 'baseball glove', 'skateboard', 'surfboard', 'tennis racket', 'bottle', '', 'wine glass', 'cup', 'fork', 'knife', 'spoon', 'bowl', 'banana', 'apple', 'sandwich', 'orange', 'broccoli', 'carrot', 'hot dog', 'pizza', 'donut', 'cake', 'chair', 'couch', 'potted plant', 'bed', '', 'dining table', '', '', 'toilet', '', 'tv', 'laptop', 'mouse', 'remote', 'keyboard', 'cell phone', 'microw*e', 'oven', 'toaster', 'sink', 'refrigerator', '', 'book', 'clock', 'vase', 'scissors', 'teddy bear', 'hair drier', 'toothbrush']# tf bilinear interpolation is different from any other's, just make doinput_sizes = [512, 640, 768, 896, 1024, 1280, 1280, 1536, 1536]
input_size = input_sizes[compound_coef] if force_input_size is None else force_input_sizedef display(preds, imgs):
for i in range(len(imgs)): if len(preds[i]['rois']) == 0: return imgs[i] for j in range(len(preds[i]['rois'])): # print("x1 y1 x2 y2",preds[i]['rois'][j])
(x1, y1, x2, y2) = preds[i]['rois'][j].astype(np.int)
cv2.rectangle(imgs[i], (x1, y1), (x2, y2), (255, 255, 0), 2)
obj = obj_list[preds[i]['class_ids'][j]]
score = float(preds[i]['scores'][j])
cv2.putText(imgs[i], '{}, {:.3f}'.format(obj, score),
(x1, y1 + 10), cv2.FONT_HERSHEY_SIMPLEX, 0.5,
(255, 255, 0), 1)
return imgs[i]# BoxregressBoxes = BBoxTransform()
clipBoxes = ClipBoxes()# Video capturecap = cv2.VideoCapture(video_src)
fourcc = cv2.VideoWriter_fourcc(*'MP4V')
fps = cap.get(cv2.CAP_PROP_FPS)
width, height = int(cap.get(cv2.CAP_PROP_FRAME_WIDTH)), int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT))
outvideo = cv2.VideoWriter('result.mp4', fourcc, fps, (width, height))
model = paddle.jit.load('inference_models/efficientDet')# predictor=predict_config("inference_models/u2netp.pdmodel","inference_models/u2netp.pdiparams")while True:
ret, frame = cap.read() if not ret: break
# print("frame shape is",frame.shape)
# frame preprocessing
ori_imgs, framed_imgs, framed_metas = preprocess_video(frame, max_size=input_size)
x = paddle.stack([paddle.to_tensor(fi) for fi in framed_imgs], 0)
x = x.astype(paddle.float32).transpose([0, 3, 1, 2]) # model predict
with paddle.no_grad():
# y=x.numpy().astype(np.float32)
# l=predict(predictor,[y])
time_start = time.time()
l=model(x) print('Time Cost:{}'.format(time.time()-time_start) , "s")
regression=paddle.to_tensor(l[-3]).astype(paddle.float32)
classification=paddle.to_tensor(l[-2]).astype(paddle.float32)
anchors=paddle.to_tensor(l[-1]).astype(paddle.float32) # print(l)
out = postprocess(x,
anch ors, regression, classification,
regressBoxes, clipBoxes,
threshold, iou_threshold) # result
out = invert_affine(framed_metas, out)
img_show = display(out, ori_imgs) # show frame by frame
# cv2.imshow('frame',img_show)
outvideo.write(img_show) if cv2.waitKey(1) & 0xFF == ord('q'):
breakcap.release()
cv2.destroyAllWindows()
cpu版的aistudio推理较慢,GPU版大约在25帧左右
具体参考我之前写的 paddle在jetson NX的配置
把efficientdet,utils和inference_models三个文件夹下载下来(里面包含了模型和目标检测所用的所有工具) 然后在板子上用以下代码即可运行efficientDet。 或者使用work文件下,我已经打包好了的
In [ ]import paddleimport cv2import numpy as npfrom efficientdet.utils import BBoxTransform, ClipBoxesfrom utils.utils import invert_affine, postprocess, preprocess_video# Video's pathvideo_src = 'video.mp4' # set int to use webcam, set str to read from a video filecompound_coef = 0force_input_size = None # set None to use default sizethreshold = 0.2iou_threshold = 0.2obj_list = ['person', 'bicycle', 'car', 'motorcycle', 'airplane', 'bus', 'train', 'truck', 'boat', 'traffic light', 'fire hydrant', '', 'stop sign', 'parking meter', 'bench', 'bird', 'cat', 'dog', 'horse', 'sheep', 'cow', 'elephant', 'bear', 'zebra', 'giraffe', '', 'backpack', 'umbrella', '', '', 'handbag', 'tie', 'suitcase', 'frisbee', 'skis', 'snowboard', 'sports ball', 'kite', 'baseball bat', 'baseball glove', 'skateboard', 'surfboard', 'tennis racket', 'bottle', '', 'wine glass', 'cup', 'fork', 'knife', 'spoon', 'bowl', 'banana', 'apple', 'sandwich', 'orange', 'broccoli', 'carrot', 'hot dog', 'pizza', 'donut', 'cake', 'chair', 'couch', 'potted plant', 'bed', '', 'dining table', '', '', 'toilet', '', 'tv', 'laptop', 'mouse', 'remote', 'keyboard', 'cell phone', 'microw*e', 'oven', 'toaster', 'sink', 'refrigerator', '', 'book', 'clock', 'vase', 'scissors', 'teddy bear', 'hair drier', 'toothbrush']# tf bilinear interpolation is different from any other's, just make doinput_sizes = [512, 640, 768, 896, 1024, 1280, 1280, 1536, 1536]
input_size = input_sizes[compound_coef] if force_input_size is None else force_input_size# function for displaydef gstreamer_pipeline(
capture_width=1280,
capture_height=720,
display_width=1280,
display_height=720,
framerate=60,
flip_method=0,):
return ( "nvarguscamerasrc ! "
"video/x-raw(memory:NVMM), "
"width=(int)%d, height=(int)%d, "
"format=(string)NV12, framerate=(fraction)%d/1 ! "
"nvvidconv flip-method=%d ! "
"video/x-raw, width=(int)%d, height=(int)%d, format=(string)BGRx ! "
"videoconvert ! "
"video/x-raw, format=(string)BGR ! appsink"
% (
capture_width,
capture_height,
framerate,
flip_method,
display_width,
display_height,
)
)
def display(preds, imgs):
for i in range(len(imgs)): if len(preds[i]['rois']) == 0: return imgs[i] for j in range(len(preds[i]['rois'])): # print("x1 y1 x2 y2",preds[i]['rois'][j])
(x1, y1, x2, y2) = preds[i]['rois'][j].astype(np.int)
cv2.rectangle(imgs[i], (x1, y1), (x2, y2), (255, 255, 0), 2)
obj = obj_list[preds[i]['class_ids'][j]]
score = float(preds[i]['scores'][j])
cv2.putText(imgs[i], '{}, {:.3f}'.format(obj, score),
(x1, y1 + 10), cv2.FONT_HERSHEY_SIMPLEX, 0.5,
(255, 255, 0), 1)
return imgs[i]# BoxregressBoxes = BBoxTransform()
clipBoxes = ClipBoxes()# Video capturecap = cv2.VideoCapture(gstreamer_pipeline(flip_method=0), cv2.CAP_GSTREAMER)# cap = cv2.VideoCapture(video_src)fps = cap.get(cv2.CAP_PROP_FPS)
width, height = int(cap.get(cv2.CAP_PROP_FRAME_WIDTH)), int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT))
model = paddle.jit.load('inference_models/efficientDet')while True:
ret, frame = cap.read() if not ret: break
# print("frame shape is",frame.shape)
# frame preprocessing
ori_imgs, framed_imgs, framed_metas = preprocess_video(frame, max_size=input_size)
x = paddle.stack([paddle.to_tensor(fi) for fi in framed_imgs], 0)
x = x.astype(paddle.float32).transpose([0, 3, 1, 2]) # model predict
with paddle.no_grad():
# y=x.numpy().astype(np.float32)
# l=predict(predictor,[y])
l=model(x)
regression=paddle.to_tensor(l[-3]).astype(paddle.float32)
classification=paddle.to_tensor(l[-2]).astype(paddle.float32)
anchors=paddle.to_tensor(l[-1]).astype(paddle.float32) # print(l)
out = postprocess(x,
anchors, regression, classification,
regressBoxes, clipBoxes,
threshold, iou_threshold) # result
out = invert_affine(framed_metas, out)
img_show = display(out, ori_imgs) # show frame by frame
cv2.imshow('frame',img_show)
if cv2.waitKey(1) & 0xFF == ord('q'):
breakcap.release()
cv2.destroyAllWindows()
代码解释
期望FPS为4(很慢) YOLOv4在NX上的FPS也差不多
以上就是基于efficientDet在jetson NX上实现目标检测的详细内容,更多请关注其它相关文章!
# windows
# 更大
# 一言
# 自定义
# 提出了
# 中文网
# typ
# fig
# onu
# writer
# udio
# red
# cos
# 区别
# ai
# 工具
# python
# kite
# 潜江网站建设美丽学校
# 用爬虫记录关键词排名
# 平顶山seo排名
# 养殖行业营销推广策略
# 如何找到自己的网站推广
# 丰县推广网站建设前景
# 淘宝营销推广秘诀有哪些
# 游戏推广营销视频
# 网页seo细节
# 广州企业网站推广费用
# 可以获得
# 这些都是
# 基础上
# 更高
# 动态图
相关栏目:
【
Google疑问12 】
【
Facebook疑问10 】
【
优化推广96088 】
【
技术知识133117 】
【
IDC资讯59369 】
【
网络运营7196 】
【
IT资讯61894 】
相关推荐:
改动一行代码,PyTorch训练三倍提速,这些「高级技术」是关键
讯飞星火大模型实现升级 助力通用人工智能人才培养
科学家称,面对人工智能,人类未来或只有灭亡与虚拟永生两个选择
【搞事】时隔4年 谷歌更新安卓logo 机器人头更饱满了
小岛秀夫不反对使用AI 但认为人类应该凌驾于AI
时隔 4 年:谷歌更新安卓机器人 LOGO,形象更立体
三星加速AR眼镜进程,预计明年上半年亮相
加强高质量数据供应能力,促进通用人工智能大模型领域的创新
讯飞听见会写“会议摘要”功能全面升级,AI更懂你的关注点
用人工智能技术,亚马逊为用户生成产品评论摘要,帮助他们轻松选购
OpenAI CEO 阿尔特曼到访日本,对全球 AI 协调合作表示乐观
电池比 Air 2S 大 20%,大疆 Air 3 无人机现身 FCC
ChatGPT 可以设计机器人吗?
关于开展“与AI共创未来”——2025年全国青少年人工智能创新实践活动的通知
腾讯AI首次模拟拼接三星堆文物,工作取得阶段性的成果
人工智能时代的科幻译者怎么办?“做好翻译工作的高端10%”|文化观察
AI框架生态峰会本周开幕 华为昇腾“朋友圈”再聚首 全球首个全模态大模型将登场
测试框架-安全和自动驾驶
世界人工智能大会上,科大讯飞宣布与华为联手
高质量数据推动AI场景化应用快速发展及落地
“无人驾驶船”将首次亮相世界人工智能大会,下半年或开进上海迪士尼
AI室内设计软件流行,室内设计行业如何应对效率变革
从GOXR到PartyOn,XRSPACE致力打造多元共赢的元宇宙世界
九号公司主导制定短途交通和送物机器人领域首个国际标准,标志着零的突破发布
“风乌”气象大模型科学家团队:用AI预报极端天气未来不是梦!
RoboNeo操作教程
建立元宇宙产业联盟:移动、咪咕、华为、小米等加入
网友自制 AI 版《流浪地球 3》预告片,登上 CCTV6
出门问问亮相2025世界人工智能大会,展示AI CoPilot解决方案
人工智能在服务优化方面优缺点有哪些
前特斯拉总监、OpenAI大牛Karpathy:我被自动驾驶分了心,AI智能体才是未来!
苹果头显降临,AI虚拟人的救星还是流星?
美图秀秀“AI 扩图”功能上线,可根据图像生成更大画幅
搭载星火认知大模型 讯飞听见智慧屏开启AI办公新体验
生活垃圾智能分类机器人社区展“才能”,征求居民意见
一家 380 亿美元的数据巨头,要掀起企业「AI 化」革命
参考封面|人工智能“淘金热”
石头扫拖机器人 G20 618 福利来袭:4999 元,超值配件领到手软
2025世界人工智能大会成功召开
大模型新品出现井喷,AI产业迎来新时代
昌吉市利用无人机实现全天候河道动态巡检
成功孵化首个大型模型解决方案的重庆人工智能创新中心
笔神作文声讨学而思AI大模型 称用“爬虫”技术盗取数据
生成式AI引路产业加速来袭,微美全息探索“AIGC+虚拟人”融合应用
广州团建公司方案 | 绝密飞行 → X-PLANE无人机团建主题团建
微软在 Bing 和 Edge 浏览器中拓展网购服务,帮用户选购心仪产品
上新7款产品,美图继续“蹭”AI
美图公司:Wink国内首发AI画面拓展功能
再度重仓 AI 赛道,SaaS 巨头 Salesforce 扩大 AIGC 风投基金规模
构建AI绘画网站的方法:使用API接口和调用步骤
2025-07-31

运城市盐湖区信雨科技有限公司是一家深耕海外推广领域十年的专业服务商,作为谷歌推广与Facebook广告全球合作伙伴,聚焦外贸企业出海痛点,以数字化营销为核心,提供一站式海外营销解决方案。公司凭借十年行业沉淀与平台官方资源加持,打破传统外贸获客壁垒,助力企业高效开拓全球市场,成为中小企业出海的可靠合作伙伴。

 ors, regression, classification,
regressBoxes, clipBoxes,
threshold, iou_threshold) # result
out = invert_affine(framed_metas, out)
img_show = display(out, ori_imgs) # show frame by frame
# cv2.imshow('frame',img_show)
outvideo.write(img_show) if cv2.waitKey(1) & 0xFF == ord('q'):
breakcap.release()
cv2.destroyAllWindows()